One HPC environment for every AI workload, without Kubernetes.
EVREN's compute layer is built the way supercomputing centres build theirs: bare metal, a batch scheduler and a fast fabric, run as one hyper-converged system.
No Kubernetes needed
Jobs run on bare metal in containers under Slurm, with no orchestration layer between the model and the GPU.
NVLink and InfiniBand together
GPUs inside a node talk over NVLink and NVSwitch, and nodes talk to each other over InfiniBand, in the same job.
Mixed GPU families
Clusters can be formed across different GPU generations and families, and the scheduler sends each job to the hardware that fits it.
Hyper-converged
Compute, storage and network are installed and operated as one system, so a new node joins the cluster ready to work.
Pretraining at scale
Multi-node distributed training for language, vision and audio models across the whole cluster.
Fine-tuning and evaluation
Fine-tuning, alignment and benchmark runs share the same queue and the same data.
Inference on the same hardware
Trained models are served behind an OpenAI-compatible API without moving to another platform.
Fair queues
Partitions, priorities and credits decide who runs next, and every job's use is accounted.
Pool the GPUs instead of splitting them.
One VM per engineer
GPUs are split into virtual machines with hypervisor passthrough. A VM can only use the GPUs of one server, usually eight, and they sit idle after hours.
8 GPUs per VMOne queue for the whole cluster
Every GPU joins one Slurm cluster over InfiniBand. Engineers queue their jobs, a single job can span many nodes, and the queue keeps working through the night.
72 GPUs, one queueFrom raw data to a running model, without leaving the platform.
Data
Versioning, quality scores and automatic splits for every dataset.
Labeling
Pre-labeling with SAM 3 and YOLO, collaborative annotation and quality control.
Training
Distributed training of image, audio and language models on H200s.
Image inference
Real-time detection on webcam, image and video.
LLM inference
Open-weight models behind one OpenAI-compatible API, on hardware in Türkiye.
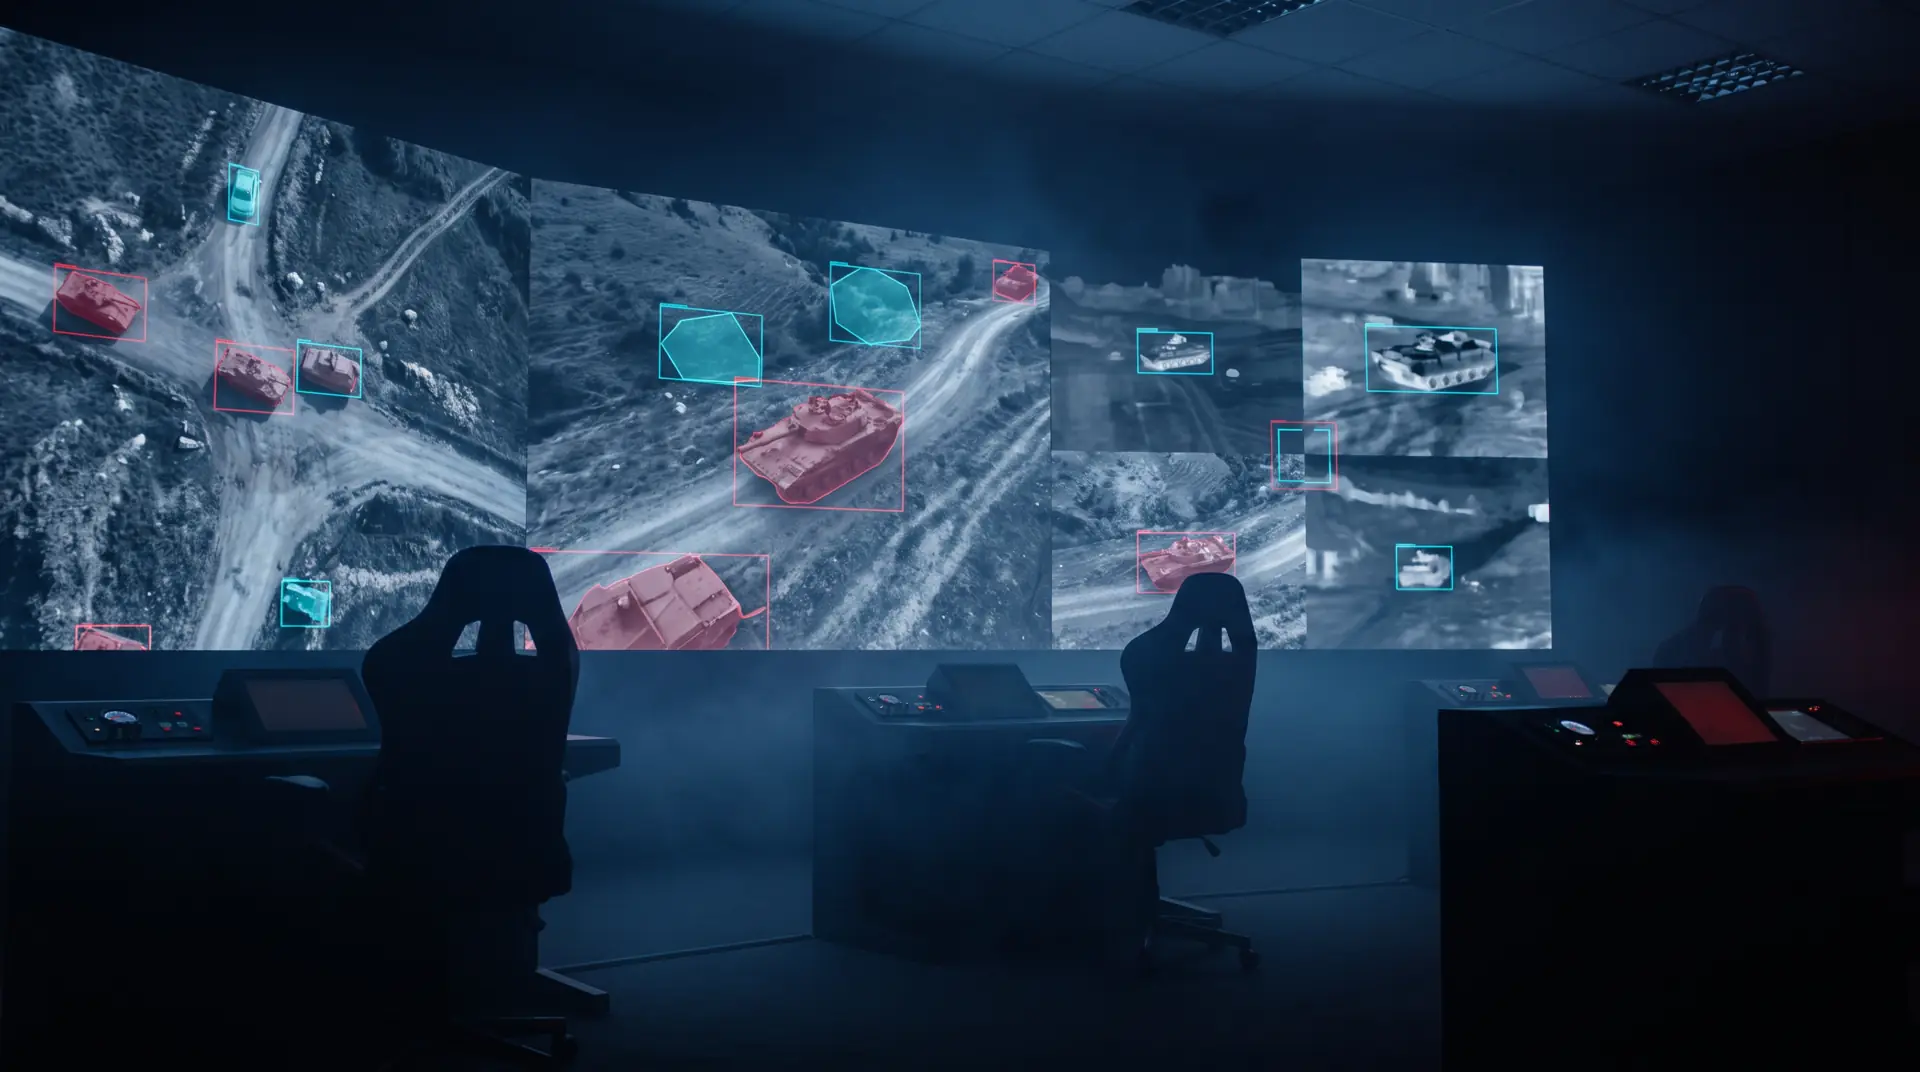
Every kind of label the sector needs.
Teams mark large datasets quickly and check each other's work in the same place.
- Bounding boxes, polygons, oriented boxes, keypoints, named-entity text labels and audio regions.
- Automatic pre-labeling with SAM 3 and YOLO cuts the time spent drawing by hand.
- Collaborative annotation with quality control, and datasets that keep their versions.
72 H200s on InfiniBand, open to the industry.
Training runs on a bare-metal HPC cluster, scheduled the way supercomputing centres do it.
- Nine nodes of eight NVIDIA H200 GPUs, each with 141 GB of HBM3e, joined by 400 Gb/s InfiniBand NDR.
- Jobs run in Apptainer containers under Slurm, with training metrics followed live.
- GPU time is paid in credits, from 10 to 35 per GPU hour depending on the tier.
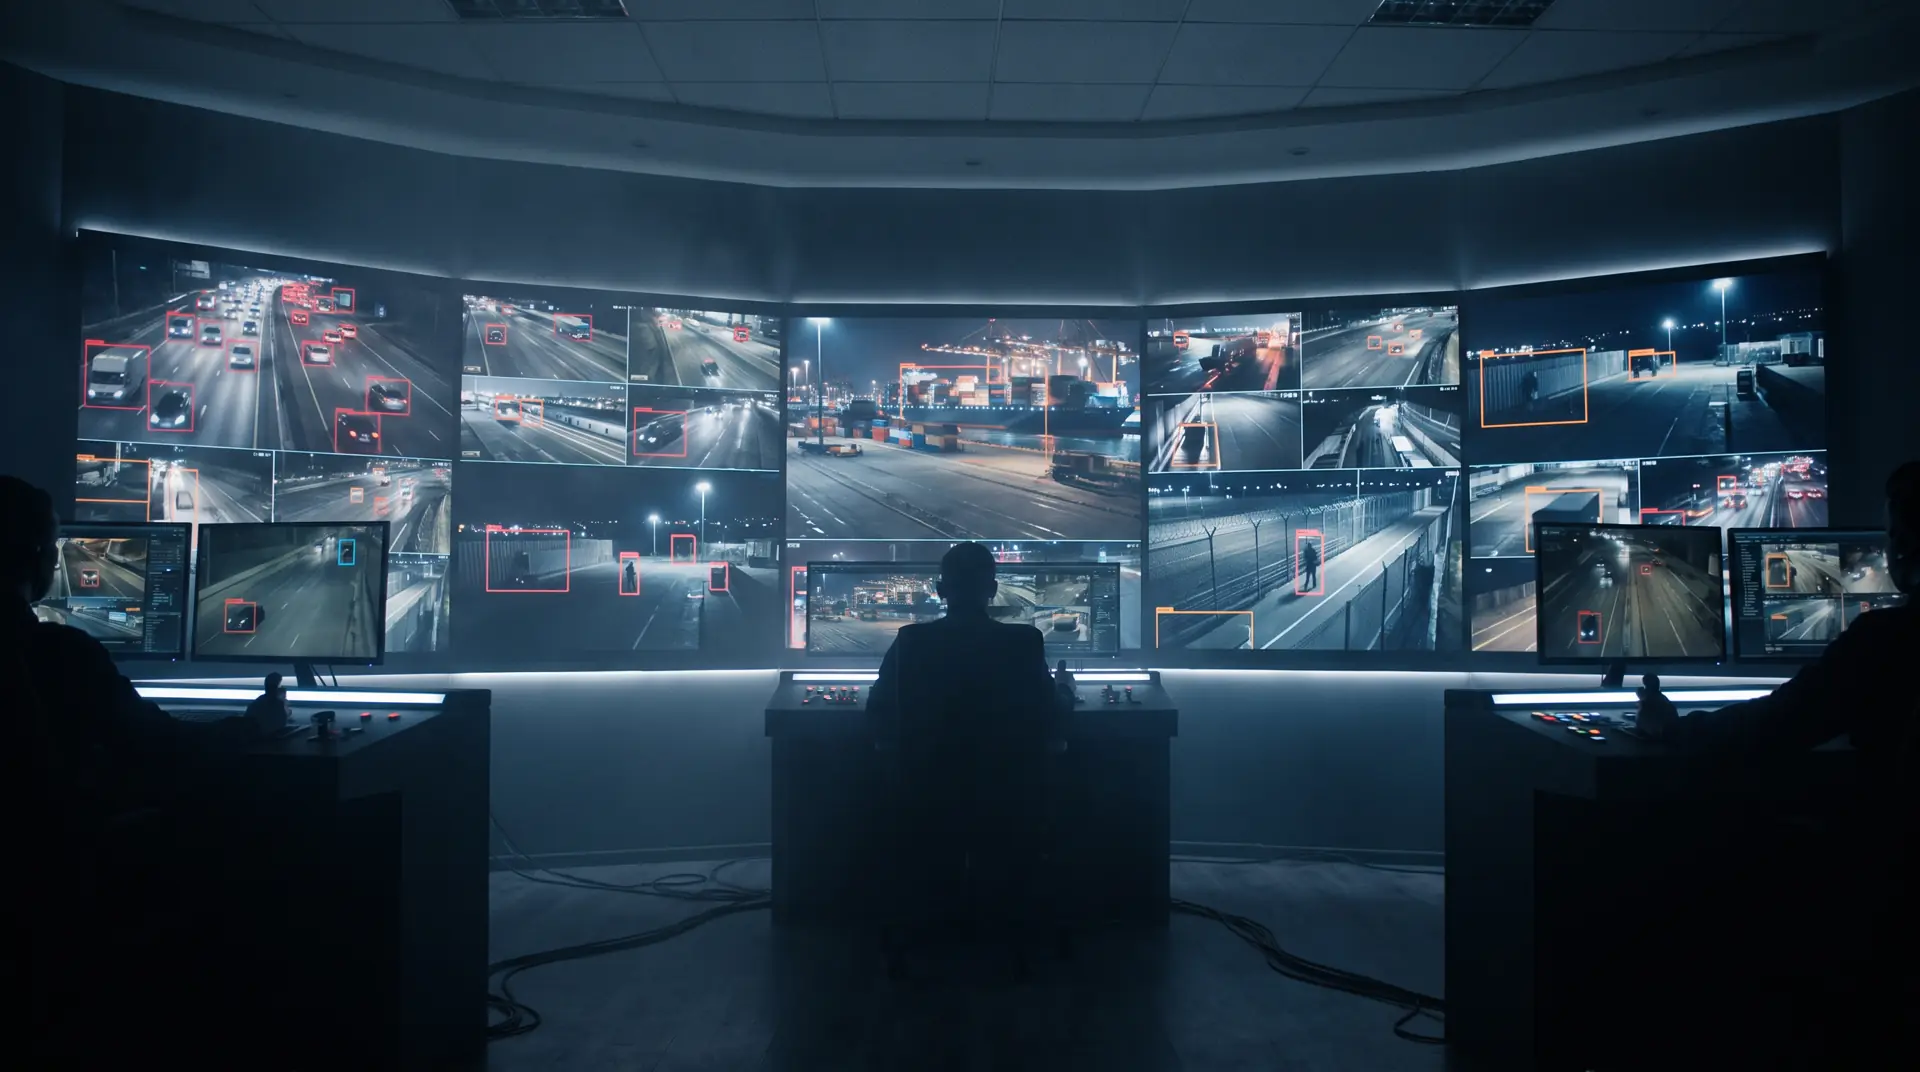
Run what you trained, the same day.
Two inference services sit on the same platform: one for images and video, one for language models.
- A dedicated server with eight A6000 GPUs runs YOLO, SAM 3 and other vision models on webcam streams, single images, batches and video, with latency under 50 ms.
- Open-weight language models for chat, coding, reasoning and visual understanding run on the H200 cluster in Türkiye, reached through one OpenAI-compatible endpoint with per-model routing and streaming.
- Data does not leave the country, and usage is governed by institutional credit controls.
Contribute data, earn compute.
Users earn credits by uploading and labeling data and sharing models, then spend those credits on GPU time. The more a team gives back to the sector's data pool, the more compute it gets.
Built for institutional use.
e-Devlet sign-in
Users sign in with e-Devlet and receive starting credits.
Roles and SSO
Single sign-on and role-based access control for teams and institutions.
Isolated data
Full data isolation between workspaces, with complete audit records.
Turkish throughout
The whole flow, from labeling to inference, runs in a Turkish interface on sovereign infrastructure.
EVREN is developed within the Presidency of Defense Industries under SSYZ, the Defense Industry AI Platform. Crudfab carries out portal, software and GPU infrastructure work within SSYZ.
Sign in with e-Devlet and start with free credits.
Go to evren.ssyz.org.tr- Building something similar?
- We design and run AI platforms and GPU infrastructure for institutions.
- hello@crudfab.com